She Rejected the AI Voice Clinicians Chose for Her Son
The voice was clear, youthful, and wrong for him. His mother’s notebook helped turn a technical choice into one he could make for himself.
October 29, 2026 · 8 min read
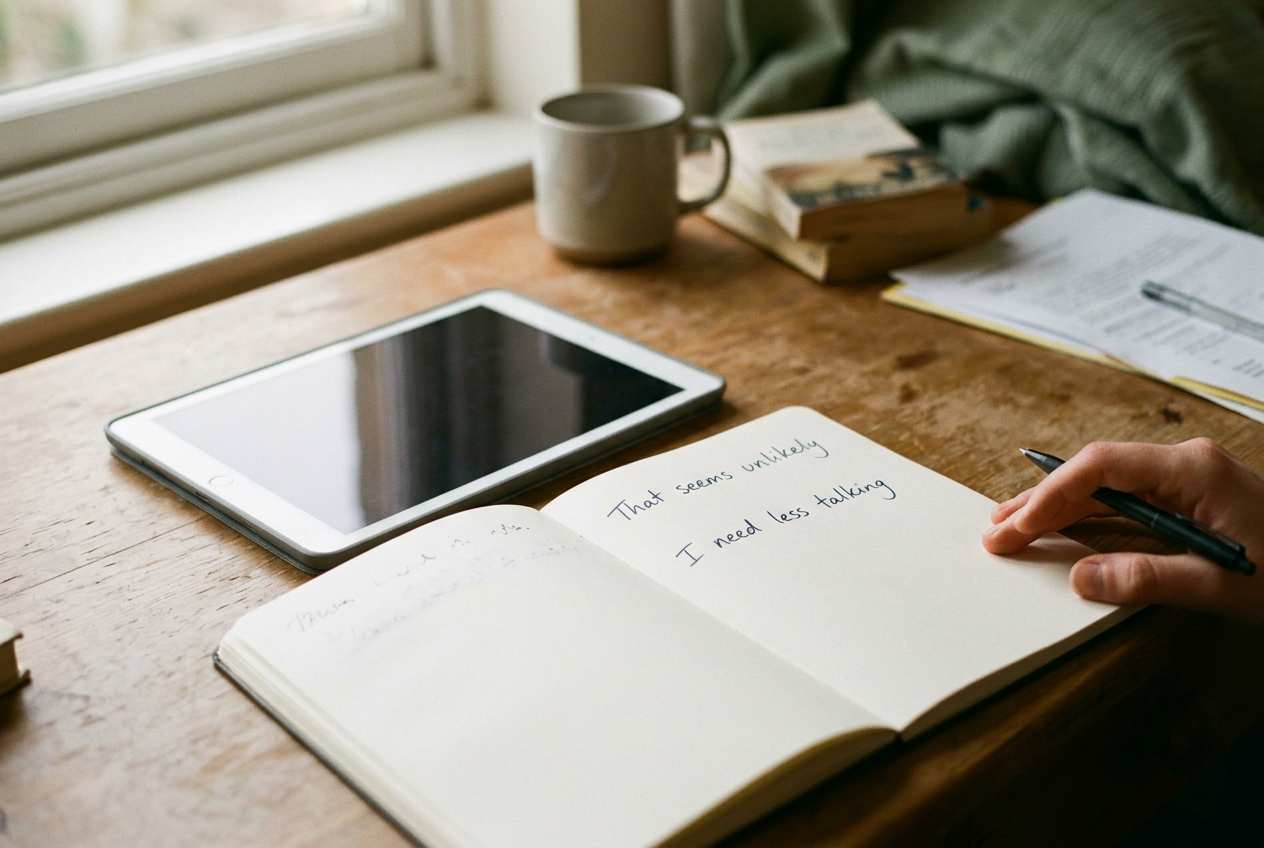
Mara brought a notebook to the appointment because her son’s best lines tended to disappear.
Some were comments he had built on his communication tablet, one word at a time. Others were phrases he pointed toward or approved while someone read possible versions aloud. She wrote down the one he chose, along with enough context to remember why the family had laughed.
The notebook held “That seems unlikely,” his answer when his father promised to fix a cabinet that weekend. It held “I need less talking,” which he used when relatives stayed past dinner. There were refusals, corrections, and lines from videos that he had altered to suit his own purposes.
Jonah was 11 and spoke few words aloud. At school and home, he used an augmentative and alternative communication device, often called AAC, to assemble language on a screen. The device could display symbols, suggest words, and read a selected sentence through a speaker.
For years, that speaker had used a standard digital voice. It was understandable but mechanical, with pauses that sometimes landed in the middle of a thought. A new voice system offered something more polished: neural text-to-speech generated by an AI model, with smoother transitions between sounds and controls for age, pitch, speaking rate, and expression.
The clinicians had selected a youthful voice with a bright tone. It pronounced Jonah’s school vocabulary cleanly. It sounded encouraging.
Mara disliked it before the demonstration ended.
The problem was not that the voice sounded fake. It sounded impressively human, which made the mismatch harder to ignore. The model lifted the ends of sentences, warmed ordinary statements with enthusiasm, and delivered jokes with the open eagerness of a child trying to make sure everyone understood that a joke had occurred.
Jonah’s humor worked another way. He waited. He offered a sentence without marking it as funny, then watched for the moment when someone caught up.
Through the cheerful generated voice, “That seems unlikely” became friendly reassurance. In Jonah’s family, spoken in their flatter rhythm, it meant that nobody believed his father would touch the cabinet.
What the voice generator had learned
A neural text-to-speech system does not store a recording of every sentence a person may want to say. It breaks typed language into units related to pronunciation, predicts features such as duration and emphasis, then generates the audio needed to speak a sentence that may never have been recorded before.
That flexibility matters for AAC users, who cannot rely on a fixed collection of prerecorded messages. Jonah needed the device to say new names, unexpected observations, and whatever he decided halfway through a conversation.
The system’s fluency came from patterns learned across large amounts of recorded speech. Depending on how a tool is built, developers may train a general model on many speakers, refine a voice using recordings from one speaker, or offer style controls that shift a generated voice within a prepared range. The result can be young-sounding without belonging to a particular young person.
That was the technical strength Mara had been shown. The voice maintained consistent pronunciation across fresh sentences and joined sounds without the clipped seams she heard in the old system.
Its failure came from the same method. A setting labeled for a child’s age could move the output toward acoustic traits commonly associated with children, while an upbeat style could add energy that listeners often interpret as warmth. Neither setting knew Jonah. The model had no access to the family’s habit of lowering their voices for the funniest sentence, or to his preference for letting a correction sit in the air.
The voice was age-appropriate as a category. Mara was listening for a person.
She opened the notebook during the demonstration and asked to hear several entries. The generated voice made “I need less talking” sound almost playful. Jonah selected the phrase again, then lowered the device volume.
Mara noticed that. She did not treat it as a complete answer. He often adjusted volume when unfamiliar audio bothered him, and she knew how easily an adult could turn one movement into a declaration he had not made.
They needed a way for him to compare the voices.
A choice he could hear
Over the next month, Mara and the support team narrowed the available options to four. She resisted the usual labels, which described voices as friendly, confident, calm, or energetic. Those words told her what the designers intended listeners to feel, not how Jonah would use the sound.
At home, she built short comparisons from the notebook. Each voice read the same phrases while Jonah listened, replayed them, and marked preferences on his device. The family changed the order because the first option sometimes benefited from being first, and they repeated the comparison on different days rather than treating one session as a final vote.
This was not a clinical test. It was a household trying to avoid choosing for him while still recognizing that choosing a voice demanded sustained attention, abstract comparison, and patience with adults who kept asking him to hear the same sentence again.
One lower, less animated voice began to hold his attention. It was not a close vocal likeness. Jonah had not recorded enough clear speech for the system to clone his natural voice, and Mara was wary of pretending that a synthetic approximation would preserve something the available data could not provide.
The preferred voice did something narrower. It left more room around punctuation. Its default expression did not brighten every statement, and when the speaking rate was reduced slightly, the pauses made his prepared lines feel deliberate rather than hesitant.
Mara returned to “That seems unlikely.” Jonah played it in the cheerful voice, then in the lower one. His father laughed at the second version. Jonah played it again.
The notebook gained a mark beside the phrase.
Voice selection had first been presented as part of configuring the device, alongside pronunciation and volume. Those settings mattered. A voice that listeners cannot understand may limit a user’s participation no matter how well it reflects a preferred style.
Yet technical quality had quietly taken over the definition of success. The cheerful voice was intelligible, smooth, and consistent. Clinicians could defend it through qualities they were used to measuring. Mara’s objection depended on timing, family speech, and the difference between sounding pleasant and sounding like someone who had chosen his words.
The AI created that tension because it could generate personality cues at scale. An older digital voice might have sounded equally mechanical for everyone. The newer system offered a convincing social presence, producing not just speech sounds but a suggestion of temperament each time it read a novel sentence.
Listeners respond to those cues even when they know the voice comes from software. A rising pitch can make a statement seem uncertain. Faster speech may feel eager. Added variation can sound expressive, though the emotion it suggests may not be the emotion the user intended.
For Jonah, those inferences affected how other people received his language. A classroom aide hearing the bright voice might soften a firm refusal into a cheerful preference. A relative might answer the apparent enthusiasm rather than the words on the screen. The system did not change his sentence, but it changed the person listeners imagined behind it.
Keeping some imperfection
After six weeks, Jonah chose the lower voice often enough that the family set it as his default. They kept two other voices available, including the cheerful one.
He sometimes selected that voice for exaggerated greetings or for reading messages he wanted to make deliberately overexcited. Mara had rejected it as his assigned identity, not as a sound he could never use. Once it became an option rather than an adult decision, Jonah found a purpose for it.
The family also stopped searching for a voice that would contain all of him. Mara had begun the process believing there must be a best match hidden somewhere in the library. The notebook showed why that standard failed. Jonah’s style lived partly in the words he chose, partly in when he released them, and partly in what the people around him already knew.
They added more of his preferred phrases to the device and adjusted pronunciations that the model handled poorly. Names were a recurring problem because text-to-speech systems often infer pronunciation from spelling and from patterns in their training data. The family supplied alternate spellings in the pronunciation controls, then listened for side effects elsewhere.
Some changes helped. Others made a familiar name sound stranger.
The lower voice was still generated from patterns drawn from other speakers. It did not belong to Jonah in the way recorded natural speech belongs to its speaker, and the family did not call it his real voice. It was a tool he could steer, one that gave him access to sentences he had never prepared and allowed him to discard a tone when it did not fit.
Months later, Mara still carried the notebook to planning meetings. It had become less a record of funny lines than evidence of use: which phrases Jonah returned to, where listeners misunderstood him, and which settings he changed without being asked.
On one page, beside “I need less talking,” she had written that he preferred the lower voice at home. A later note recorded that he used the cheerful one to interrupt a long family story.
Both entries stayed.
Questions people ask
Can an
AI voice sound natural and still be wrong for a child?
Yes. Neural speech can pronounce new sentences smoothly while adding pitch, pace, and emphasis that listeners associate with a personality. In Jonah’s case, the voice sounded youthful and clear, but its constant brightness changed how his dry humor and firm refusals were received.
How does an AI-generated communication voice work?
The system converts text into pronunciation units, predicts features such as duration and emphasis, and generates speech audio for the whole sentence. It can say phrases that were never recorded, which is valuable for open-ended communication, but its expressive habits come from training patterns and preset style controls rather than knowledge of the user.
Who gets to choose the voice on an AAC device?
In this family’s experience, clinicians narrowed the options because they understood intelligibility and device settings, while Jonah compared repeated samples and showed preferences over several weeks. His mother treated volume changes and replays as information rather than a final answer, then kept multiple voices available after he chose a default.
Can a family customize more than pitch and speaking speed?
Some systems allow pronunciation changes, style choices, or voices refined from recorded speech, though the available controls vary. Jonah’s family also customized the language around the voice by saving phrases he chose and watching how he used them. The notebook remained open beside the device, with a mark next to “That seems unlikely.”
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.