A Professor’s AI Score Penalized Students Who Paused
The seminar tool rewarded fast, frequent talk. Its score conflicted with what the professor saw: multilingual and reflective students were listening, thinking, and then losing points.
October 24, 2026 · 7 min read
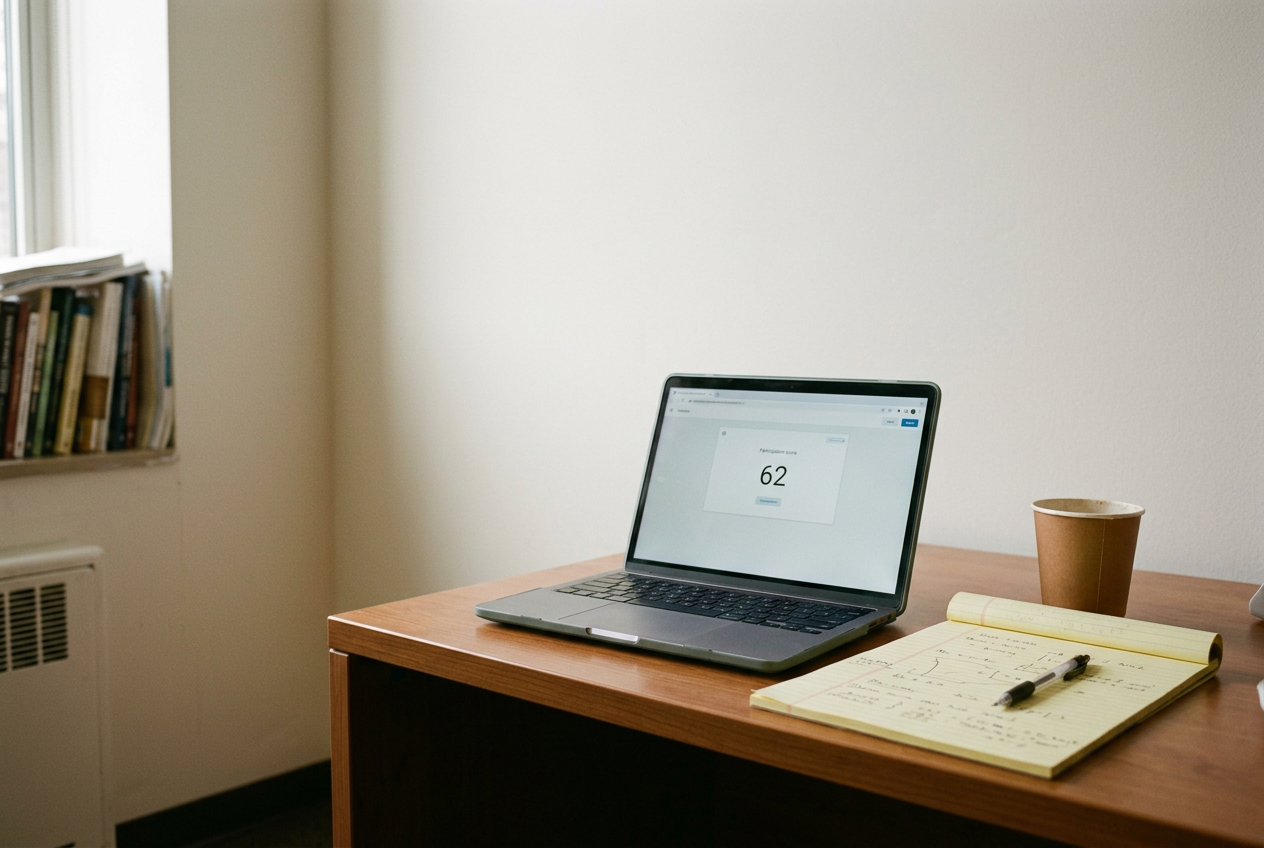
The professor found the problem at her desk after seven weeks of class, with an empty paper cup near the laptop and a stack of reading responses she had meant to finish. On the seminar dashboard, one student’s participation score was 62 out of 100.
That made no sense.
The student did not speak often, but when she did, other students wrote down what she said. She had connected a difficult reading about public memory to an earlier discussion that the rest of the class had mostly forgotten, and she tended to wait through the first rush of comments before entering. The professor’s notes beside her name included phrases such as “careful synthesis” and “brings discussion back.”
The dashboard showed a different line: response latency below the class benchmark. Her turn frequency was low, too. Several contributions had also received weak relevance scores, even though the professor remembered them as central to the discussion.
The 62 stayed on the screen.
What the system heard
The platform recorded seminar audio through the classroom microphone and separated the stream into speakers, a process generally called diarization. It matched those speaker segments to enrolled students, converted the speech into text, and used the transcript to estimate whether each contribution related to the assigned reading or the discussion already underway.
Timing mattered. The platform marked the end of a prompt, measured the silence before a student began, and treated shorter gaps as stronger evidence of engagement. It also counted turns, rewarding students who entered the conversation frequently even when each comment was brief. A relevance model supplied another part of the score by comparing transcript passages with course materials and prior remarks.
A spreadsheet could count raised hands if someone entered them. This system created data that had not existed before: it decided where one voice stopped, which student owned the next segment, whether the words were on topic, and whether the silence before them meant thought or disengagement. Those inferences produced the 62.
The professor had agreed to use the platform because participation grades had always troubled her. Students wanted to know what counted, while instructors across the program applied different standards. The dashboard promised a consistent record, and its weekly summaries were easier to defend than a margin note made while someone else was speaking.
At first, it even helped. The speaking map showed that the professor returned to the same confident students, often without noticing. After she began waiting longer and inviting written responses before discussion, more people entered the room’s conversation. She kept the map open after class because it caught a habit she had missed.
Then she looked closely at who remained near the bottom.
The pattern was not universal, but it was plain enough. Several multilingual students had low response-speed measures. So did two students whose written work was strong and whose spoken contributions usually arrived after the conversation had developed. Fast speakers accumulated turns by offering an initial reaction, a correction, or a quick agreement.
The system read each entry as another sign of engagement.
The student with the 62 often waited until she had a complete sentence.
Speech recognition added another problem. When the transcription model was less confident about her phrasing, it dropped words or divided one contribution into fragments. The relevance model then compared an incomplete transcript with the reading and sometimes found a weak match. A thoughtful comment could be penalized twice: first for arriving late, then for being transcribed badly.
The dashboard did not say that the student was unprepared. It did not need to. The overall score fed into the gradebook’s participation column, where a low number carried that implication without explaining how it had been assembled.
The useful metric and the wrong conclusion
During the next seminar, the professor placed her laptop beside a legal pad and watched without opening the dashboard. A question about an essay produced several immediate answers. One student spoke twice before the quieter student lifted her hand, lowered it when another voice entered, and tried again later.
There was a pause when the professor called on her. She looked at the marked page in front of her, began one sentence, revised its opening, and then made the connection the class had been circling. The professor drew a line beside the student’s name.
Afterward, the dashboard had recorded a delayed response and one relevant turn. It did not register the abandoned attempt to enter earlier, the page of notes, or the way later comments borrowed her distinction. The platform could infer speech from sound. It could not infer the work done in silence.
The professor brought the 62 to a meeting about grading consistency. The response was not a command to trust the machine, at least not in those words. She was reminded that instructors could adjust grades and that the institution valued comparable measures. Manual changes would remain visible, which meant she might be asked why her participation results departed from the automated record.
That was the choice hidden inside the convenience. She could accept a score built from repeatable signals that were only partly related to learning, or she could use her own observations and produce a result that looked less standardized from outside the classroom.
She returned to the dashboard and reviewed the student’s flagged contributions alongside the audio. In one, the transcript had omitted the key noun. In another, the system attached the opening phrase to a nearby speaker, leaving the student’s remaining sentence too thin for the relevance model. The line still read 62 out of 100 because the tool treated its own transcript as the event.
For final grades, the professor replaced the automated participation score with a judgment based on her notes, submitted work, and the substance of students’ contributions. She kept the speaking map because it showed who received room to talk, but she stopped using response speed as evidence of engagement. The institution’s preferred metric remained available in the gradebook, now beside a manual adjustment.
The decision did not settle her discomfort. Her notes were incomplete. Memory favors the vivid comment, and a professor can mistake fluency for understanding without any software involved. The dashboard had exposed one of her biases while introducing another, which made it harder to dismiss and harder to trust.
Near the end of the term, the student with the 62 came to discuss a paper. She did not ask about the participation score. She opened her notebook, found a marked passage, and paused before explaining why she thought the author’s conclusion failed.
The professor waited.
Questions people ask
How can AI measure classroom participation?
These systems can identify speakers from classroom audio, transcribe their words, count speaking turns, and measure the gap after a prompt. Some also use language models to estimate whether a comment relates to assigned material. The final score combines inferences, not a direct measure of attention or learning.
Why would a pause lower a participation score?
A platform may treat quick responses as evidence that a student is attentive and ready to contribute. That assumption disadvantages people who formulate a full answer before speaking, translate between languages, or wait for an opening rather than interrupting. In this seminar, response delay directly pushed some scores down.
Can speech recognition errors affect participation grades?
Yes. Missing words, incorrect speaker assignments, and fragmented sentences can change what a relevance model evaluates. Here, an incomplete transcript made a student’s comment look less connected to the reading, even though the classroom audio and the professor’s notes showed that it addressed the central argument.
Did the professor stop using the platform?
No. She kept the speaking map because it revealed whom she called on repeatedly, but she stopped using the automated score to determine participation grades. The platform remained attached to the gradebook, and the original row still displayed 62 out of 100.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.