Two Pregnancy Chatbots Disagreed. The Couple Made a Source Rule.
One assistant warned against a planned trip while another offered reassurance. A notebook helped the expectant parents see that a confident tone was not the same as reliable evidence.
October 12, 2026 · 8 min read
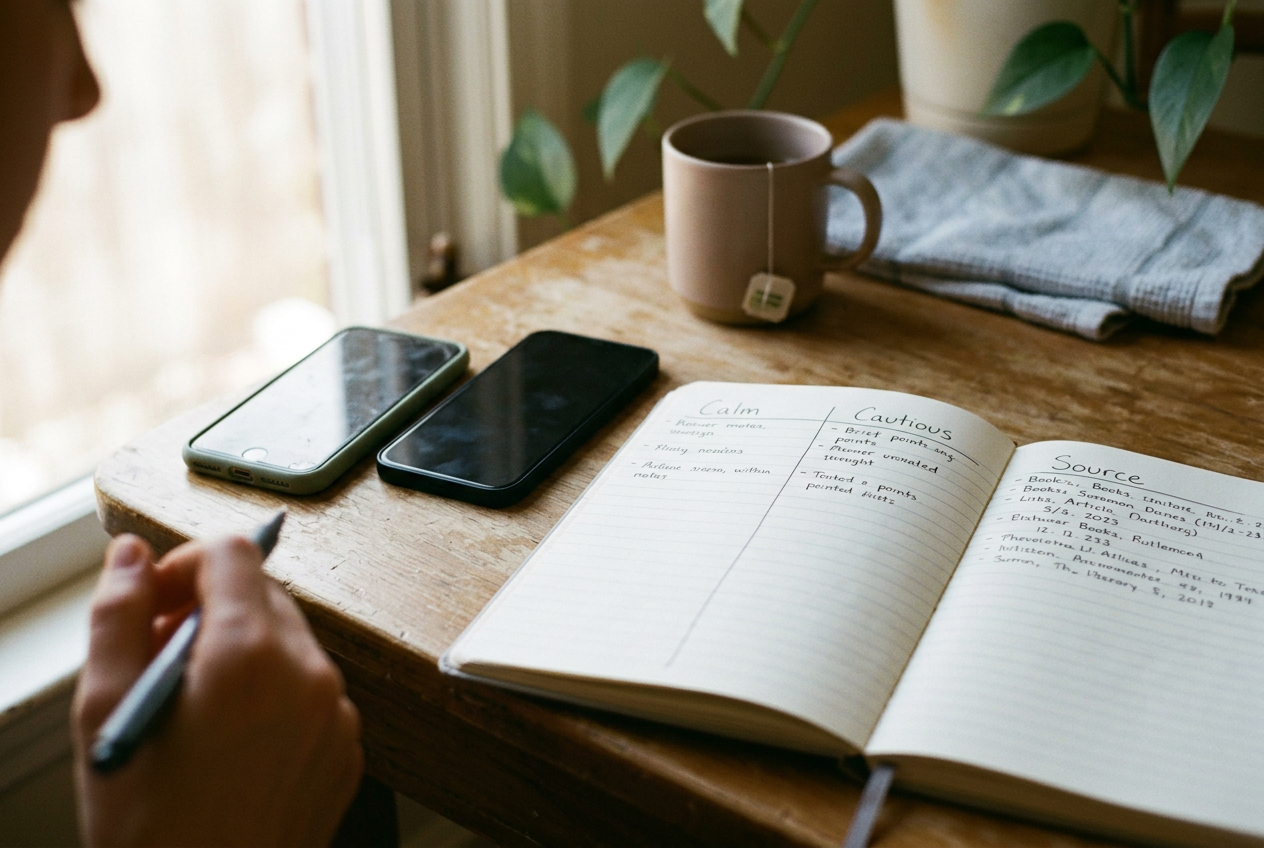
At 28 weeks pregnant, Mara began keeping a notebook beside the chair where she and Ben usually planned for the baby.
It had started as a place for practical things: what they had bought, which expenses could wait, and what they wanted to ask at the next prenatal appointment. Six weeks later, eleven pages held paired summaries from two AI parenting assistants.
Mara called the columns Cautious and Calm.
The labels were unfair, though not entirely. The assistant she used tended to foreground possible risks, recommend checking with a professional, and attach links to health organizations. Ben's preferred assistant answered in a warmer, more conversational register. It often emphasized how common an experience was before adding qualifications farther down.
Neither tool had examined Mara. Both could produce fluent, personalized replies after receiving a due month, a symptom description, or a detail from an earlier exchange. That ability was what made the disagreement feel personal rather than generic.
Their first serious split concerned a four-hour drive they hoped to take during the third trimester. Mara told her assistant how far along she would be, mentioned a recent discomfort, and asked whether the trip sounded sensible. Its response was cautious enough that she began thinking they should cancel.
Ben entered a shorter version into his assistant. He described an uncomplicated pregnancy and asked whether people commonly made similar trips. His answer was reassuring, with a brief note that individual circumstances could change the picture.
They sat with both screens open.
The assistants had not merely delivered different facts. Each had assembled an answer around the frame it received, one emphasizing a symptom and uncertainty, the other emphasizing normality and precedent, while their distinct instructions and source systems also shaped which cautions appeared first.
Ben heard Mara's tool as alarmist. Mara heard his as eager to please.
The notebook fills
The disagreement did not stay with the trip. It moved into ordinary preparation, where almost every decision could be phrased as a safety question.
They compared answers about a household product, sleep preparation, and whether a common physical change belonged on their appointment list. Mara's assistant tended to produce thresholds and caveats. Ben's often began with reassurance, then asked a follow-up that made the exchange feel attentive.
Over six weeks, the notebook reached 23 entries.
Mara wrote only short summaries, never whole transcripts. Beside each one, she marked whether the assistant had linked to a source, named the date of that material, or acknowledged that it lacked enough information. She also added the wording they had used in their prompts, a detail that first seemed fussy and then became the most revealing part of the page.
When the same person asked both assistants the same question in nearly the same words, the answers moved closer together. They did not always agree, but the sharpest conflicts often softened.
That discovery did not settle the argument. Ben still preferred the assistant that left him feeling capable, particularly after evenings spent reading about rare outcomes they had no reason to expect. Mara did not enjoy being frightened, but she trusted an answer more when it showed where the caution came from.
Each believed the other was choosing a mood and calling it judgment.
The notebook made that accusation harder to sustain, because it showed that both of them changed their prompts. Mara included details that invited risk assessment. Ben asked broader questions about what was typical. Their assistants then responded to those differences while preserving a conversational tone that made each result sound more settled than it was.
Why the assistants could disagree
A conversational AI does not necessarily pull a finished answer from a single approved medical page. Many systems generate text by predicting likely language from patterns learned during training, sometimes adding current material retrieved from a selected collection of websites or documents.
The result depends on more than the topic. System instructions can tell an assistant to prioritize caution, empathy, brevity, or engagement. Retrieved sources may differ. Earlier messages can remain in the conversation context, which means an assistant may respond to information a user no longer realizes is affecting the exchange.
Prompt framing matters too. A request centered on danger invites a different answer from one centered on how common an activity is, even when both describe the same plan.
Most important for Mara and Ben, fluent language did not show how well supported an answer was. A calm paragraph could rest on broad generalization. A stern warning could reflect a safety setting designed to avoid overlooking a low-probability concern, rather than evidence that the concern applied to Mara.
Neither tone supplied a reliable measure of confidence.
The assistants also behaved differently when challenged. Mara's tool usually repeated its caution and offered source links. Ben's sometimes revised its emphasis after he asked for evidence, acknowledging uncertainty that had barely appeared in its first response.
That unsettled him more than the initial disagreement. He had assumed the first answer represented the tool's considered position, but the conversation showed that its presentation could shift in response to the user's pressure without any new fact entering the exchange.
The AI was not holding a private medical opinion. It was generating a plausible continuation under changing instructions and context.
What they had already shared
The notebook introduced another discomfort. Its prompt column showed how much personal information they had entered while trying to make generic tools more useful.
Mara had shared her week of pregnancy and symptoms. Ben had described parts of her health history in his own account, assuming that removing her name made the exchange anonymous enough.
Together they read the tools' privacy summaries. The policies differed and could change, but both made them notice that conversation histories might be stored, reviewed for safety, or used to improve systems depending on the service and its settings. Deleting a visible chat did not necessarily explain every stage of data retention in language they found clear.
They had not uploaded records or ultrasound images. Until then, that had been their definition of restraint.
The notebook showed a broader picture. A pregnancy timeline combined with symptoms, travel plans, and family circumstances could still be intimate, even without a name attached, and Ben realized he had disclosed details about Mara from an account she did not control.
She was not furious. She wanted him to ask first.
After that conversation, they stopped putting fresh health details into general-purpose assistants. They still used them to turn a packing idea into a shorter checklist, compare broad categories of baby gear, and draft questions they could carry into an appointment. Those uses reduced mental load without asking the machine to decide what a symptom meant.
Ben kept his preferred assistant. He liked its manner and did not regard that preference as a mistake.
The source rule
Their next prenatal visit did not produce a verdict on which assistant was better. They brought the travel question and a few notebook entries, then learned how much relevant context had been absent from both chats.
The clinician considered Mara's own history and current symptoms, asked follow-up questions, and pointed them toward patient information from established medical organizations. The conversation was specific to her circumstances. Its purpose was not to grade the bots.
At home, Mara drew a line beneath entry 23.
They agreed that a medical-sounding claim would not enter their shared plans unless they could trace it to a source they had already decided to trust, or raise it with a qualified professional who knew Mara's situation. Agreement about authority came before whichever answer felt better.
The rule reduced a particular kind of friction. They no longer arrived at breakfast carrying rival paragraphs and expecting the other person to identify the winner from tone alone.
Some uncertainty remained. Official sources could be broad, appointments were limited, and they still had different tolerances for caution. A source rule did not make them temperamentally alike.
It did change the notebook. Later entries included a third column labeled Source, with room for an organization, a publication date, or the words for appointment. Calm and Cautious stayed on the page, but neither column got the final word.
Questions people ask
Why can two pregnancy chatbots give opposite answers?
Generative assistants can use different system instructions, source collections, safety settings, and conversation histories. Small changes in a prompt can also shift what the system emphasizes. In Mara and Ben's notebook, questions framed around risk drew stronger warnings, while questions framed around what was common drew more reassurance.
Does a confident AI answer mean the evidence is strong?
No such link appeared in their experience. Both assistants produced smooth, definite language even when relevant personal context was missing. One became more uncertain only after Ben requested evidence, showing that conversational confidence can reflect presentation choices rather than a measured level of medical certainty.
Is it private to discuss pregnancy with an AI assistant?
Privacy depends on the service, account settings, retention practices, and information entered. Mara and Ben learned that removing a name did not make a detailed pregnancy timeline feel nonpersonal, especially when symptoms and family plans accumulated across a conversation. They began treating those combined details as sensitive.
How did they keep using
AI without letting it settle medical questions?
They used the assistants for lower-stakes tasks such as shortening packing notes and drafting topics to discuss with a clinician. Claims affecting health or safety went into the notebook until they could identify an agreed source or raise them during an appointment. Their final entry records the source beside the answer.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.