Two Parenting AIs Split an Expectant Couple Over a Bassinet
One assistant treated a used bassinet as unsafe. Another approved it with confidence. The disagreement taught an expectant couple to compare sources before trusting tone.
October 12, 2026 · 7 min read
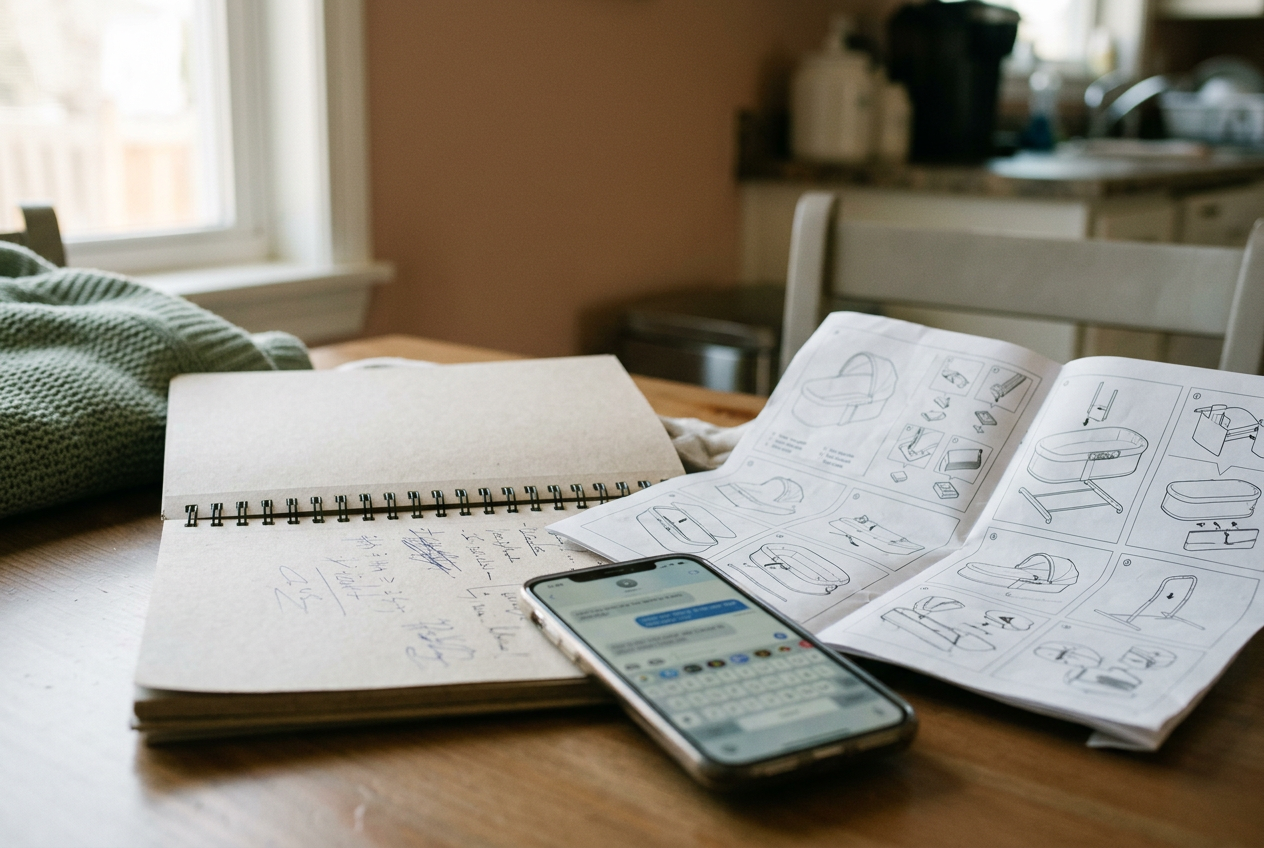
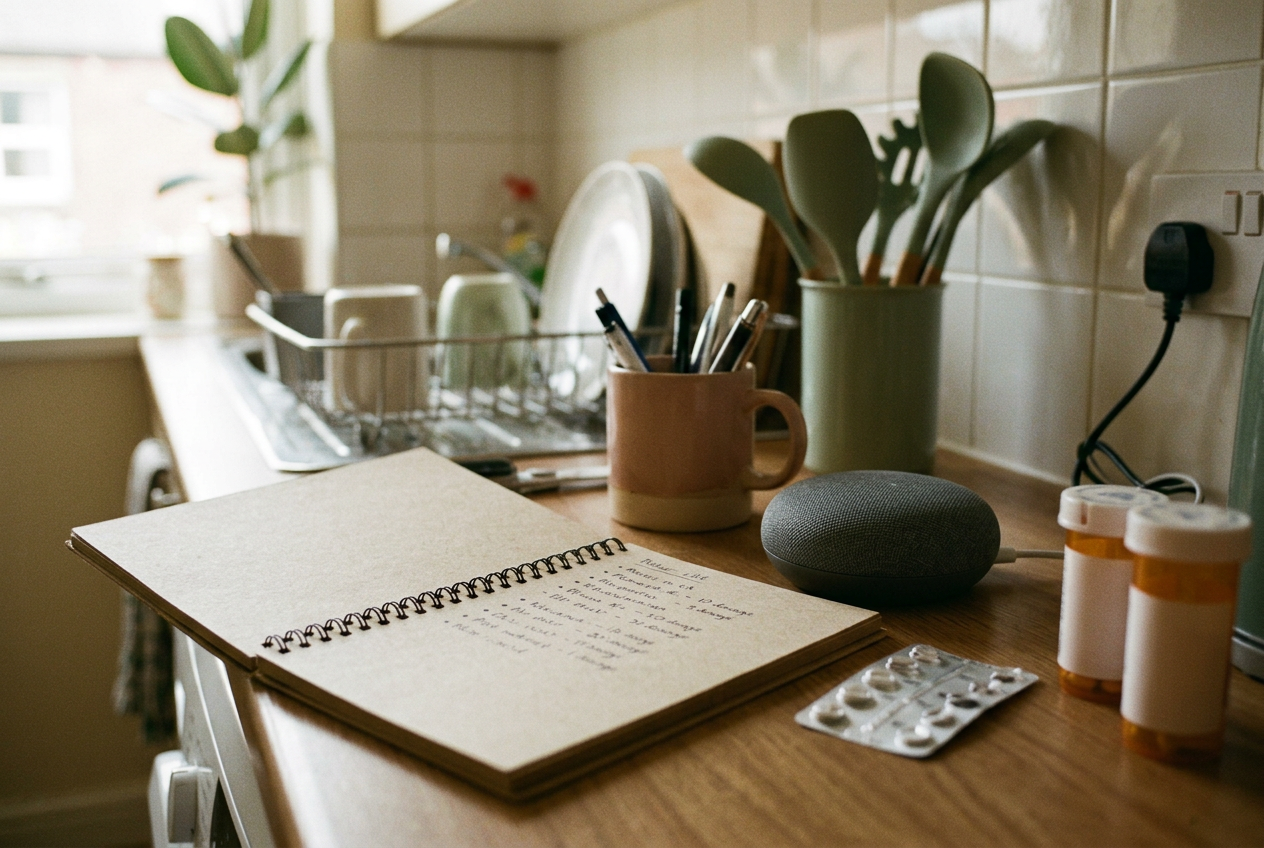
At 29 weeks pregnant, Mara kept a notebook on the kitchen table. It held the questions that arrived between appointments, when a thought about feeding or sleep became difficult to set aside.
Eli had drawn a line down one page. One side was labeled “ask the clinician.” The other said “look up.”
The system worked until a relative offered them a used bassinet.
It looked clean. The mattress felt firm, and the frame had no visible damage. Mara wanted to check whether its age mattered and whether they could add a waterproof cover beneath the fitted sheet. She wrote “used bassinet” in the notebook, then opened the parenting assistant she had been using for two months.
Her assistant was cautious. After she entered the age of the bassinet and described the mattress, it advised against using secondhand sleep equipment unless its history and current compliance could be confirmed. Its answer expanded into possible hazards and suggested checking with a medical professional.
Mara circled the notebook entry.
Eli thought the answer sounded broad. He opened a different parenting assistant, one he preferred because it tended to explain what was common without making every uncertainty feel urgent. He pasted in the same question, including the details Mara had supplied.
His assistant said the bassinet was probably fine if it remained stable and the mattress fit closely. It also treated a thin waterproof layer beneath a fitted sheet as a reasonable precaution.
The answers did not merely differ in emphasis. One rejected the bassinet unless they could establish more about it. The other approved the setup they had described.
That evening, an ordinary object became a dispute about judgment. Mara heard Eli’s answer as permission assembled from missing facts. Eli heard hers as another warning that offered no usable measure of risk.
Neither of them had intended to appoint a chatbot as the final authority. Yet each assistant had remembered earlier conversations, responded in a familiar tone and placed the new question inside a continuing account of the pregnancy. The tools sounded less like search boxes than steady correspondents.
That was part of their pull.
Why the answers felt personal
Both tools generated conversational responses by predicting likely language from the prompt, their prior chat context and the instructions their developers had given them. They could turn a few ordinary details into a tailored explanation, even though neither had examined the bassinet, verified its model or seen the couple’s medical information.
Mara’s assistant regularly foregrounded uncertainty. It often directed pregnancy and infant-safety questions toward professional care or official guidance, and its answers appeared shaped by a policy that favored caution when harm was possible.
Eli’s assistant handled uncertainty differently. It acknowledged limits, then moved quickly toward a practical answer. Its reassuring language did not mean it possessed better evidence. It reflected how the system framed incomplete information and what kinds of responses it had been tuned to produce.
The couple could see some of that only after they compared the chats. Mara’s answer linked to an official safe-sleep resource, though it also made the unsupported leap that a used bassinet should generally be rejected. Eli’s included links to broad parenting articles, and some had no visible publication date.
More important, his assistant had inferred that “in good condition” meant the bassinet met current guidance. Mara and Eli had used the phrase to mean that nothing looked broken. The tool converted their casual description into a safety conclusion it could not verify, then wrote its approval without preserving that gap.
A spreadsheet could have stored two recommendations. It could not have created this particular conflict. The assistants produced responsive arguments in different emotional registers, remembered which concerns each partner had raised before, and made each person feel that the machine understood the kind of parent they were trying to become.
Mara returned to the notebook. Beneath “used bassinet,” she wrote the source attached to each answer and whether the assistant had stated what it did not know. The page no longer recorded a single task. It showed two chains of authority.
Comfort became part of the evidence
The disagreement lingered because the assistants matched needs neither partner had named.
Mara had found pregnancy full of thresholds she could not see. Her tool’s caution gave those thresholds shape. It identified possibilities she had not considered and let her place them somewhere outside her own mind.
Eli had begun to dread answers that treated normal preparation as a field of hidden dangers. His assistant made parenthood seem manageable. It separated common situations from emergencies and often left him with one concrete next step.
For a while, they argued about which assistant was “better,” although the word concealed what each wanted from it. Mara valued an answer that preserved uncertainty. Eli valued one that helped them continue with the day.
They tested the tools again using another line from the notebook, this one about a heating pad Mara sometimes used for back discomfort. Small changes in wording produced noticeably different boundaries. When the prompt emphasized pregnancy, the cautious assistant raised more concerns. When Eli described brief use and low heat, the reassuring assistant leaned toward acceptance.
The systems were not consulting a shared, fixed rule and translating it into different prose. Each response was newly generated from the wording, the preceding conversation and whatever sources or policies the tool could access. A fluent answer could vary while retaining the same composed voice.
That discovery unsettled Eli more than the first disagreement. He had treated consistency of tone as a sign that the reasoning underneath was stable.
Mara noticed something else. Their long chats contained gestational timing, symptoms she had experienced and details about products they owned. They had entered those facts gradually, in exchanges that felt private because they resembled conversation. Neither had stopped to learn how long the platforms retained chats or whether conversations could be used to improve the systems.
They opened the account settings and privacy explanations together. The language did not answer every concern they had. They deleted older conversations where the controls allowed it and stopped including names, appointment details and other information that was not necessary for a general question.
This did not make the assistants useless. It changed the job they were allowed to do.
A shared source came before a shared answer
The bassinet remained beside the kitchen wall for another week. Mara and Eli looked up the manufacturer’s current instructions and checked an official safe-sleep source cited by their care team. The waterproof layer described by Eli’s assistant did not match the instructions for that bassinet, and the available information did not establish whether all its parts were original.
They decided not to use it.
The cautious assistant had landed nearer their decision, but Mara did not count that as proof that it was trustworthy in every future exchange. Its broad warning about used equipment had gone beyond the evidence it showed. A system could reach a defensible outcome through weak reasoning, just as another could produce a comforting mistake from a plausible assumption.
In the notebook, Eli crossed out the two columns. On a fresh page, they wrote the sources they were both willing to treat as primary for medical and infant-safety questions: their care team, current manufacturer instructions and official public-health material. The assistants could help them find terms to research or organize questions, but the couple would not settle a disagreement by choosing whichever response better fit the mood of the evening.
That boundary reduced one kind of argument. It did not make them agree on how much caution was enough.
Eli still used his assistant. He asked it to summarize long articles and turn broad concerns into questions he could bring to an appointment. Mara kept hers for checklists, while noticing how often its risk-sensitive style made rare possibilities feel close.
The notebook stayed on the table. Several weeks later, “bottle cleaning” appeared in Mara’s handwriting, followed by two source links and an empty space for what their clinician said.
Questions people ask
Why can two parenting AI assistants give opposite answers?
Generative assistants build responses from the wording of a prompt, prior chat context, developer instructions and any sources available to them. Different safety policies or source collections can push one tool toward caution and another toward reassurance, even when both receive the same basic facts.
Does a confident
AI answer mean it verified the product or situation?
No such verification occurred in Mara and Eli’s chats. The reassuring assistant inferred that their phrase “in good condition” meant the bassinet satisfied current safety guidance, although they meant only that it looked intact. Its fluent wording hid the fact that this key assumption had never been checked.
Can parenting assistants replace medical or infant-safety guidance?
This composite experience does not provide medical advice, and the couple did not treat either tool as a replacement for professional care. They used current manufacturer information, official guidance and their care team for consequential decisions, while keeping the assistants in a supporting role.
What privacy issue did the couple overlook?
They had gradually shared pregnancy timing, symptoms and household details because each exchange felt like a private conversation. After reading the platforms’ settings and privacy explanations, they removed older chats where possible and left identifying or appointment-specific details out of the notebook prompts they used later.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.