College AI Gave Her 11 Nearby Options. Her Counselor Checked Why.
Planning software ranked nearby colleges as the practical choices for a first-generation student. A counselor tested which assumptions had pushed more selective schools out of view.
October 17, 2026 · 7 min read
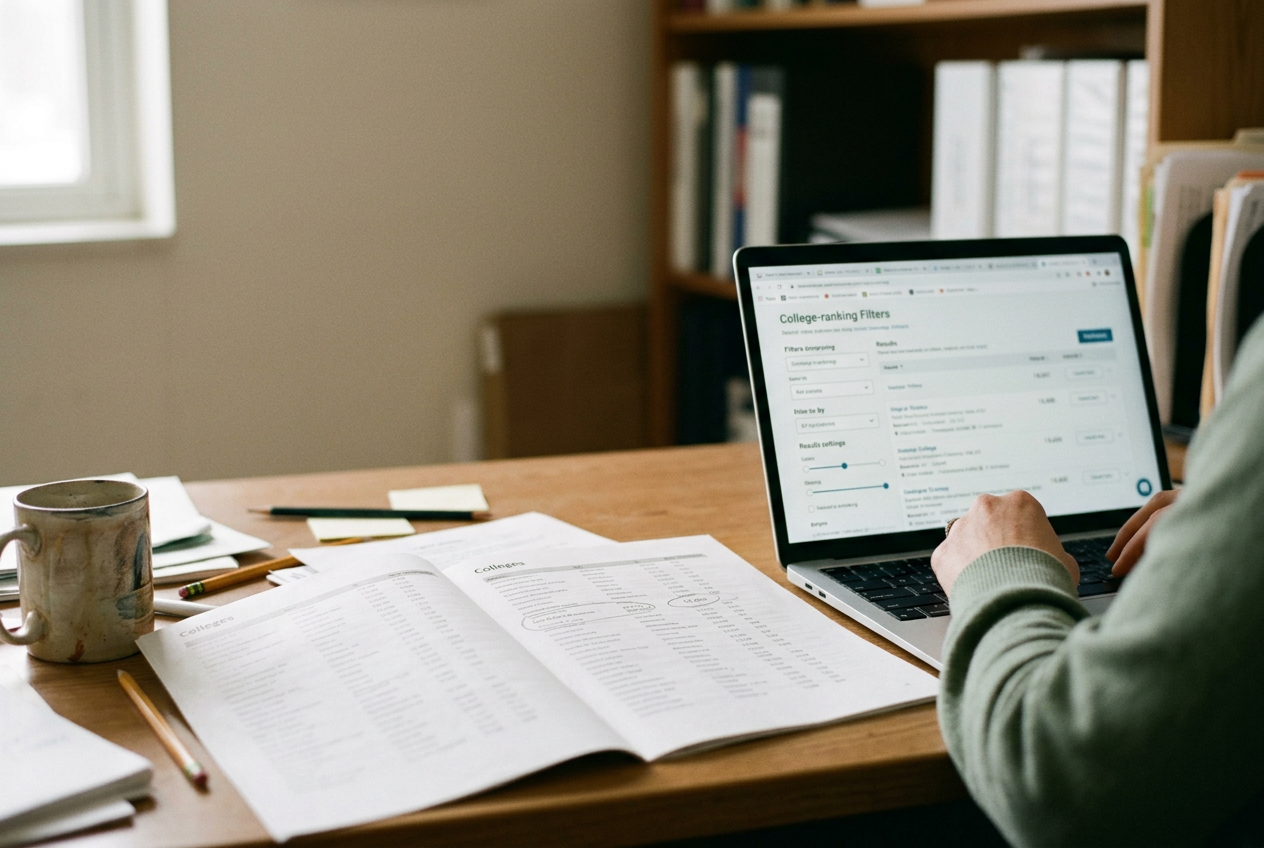
The two-page college list came off the printer late in the school day, after the hallway had thinned out and someone nearby had started dragging chairs across a classroom floor. Marisol, a high school senior, held the first page by its corner. It showed 11 recommended colleges. Every one was within 75 miles of home.
Her counselor, Ms. Reed, noticed the number Marisol had circled in pencil: $18,400. That was the software’s estimated yearly net cost for a nearby public college, after grants and scholarships. The college was labeled a strong overall fit, with a high predicted chance of admission.
Marisol’s grades were above its usual range.
The list was not absurd. That made it harder to dismiss.
Marisol had a 3.78 GPA, worked about 14 hours a week at a grocery store, and lived with a parent whose annual income was $38,600. Nobody in her immediate family had completed a four-year degree. She wanted to study public health and had mentioned a selective university about 600 miles away, partly because its website described substantial aid for families with low incomes.
It did not appear anywhere on the printout.
Ms. Reed first wondered whether Marisol had accidentally hidden it. Then she opened the planning dashboard and found a phrase she could not parse from the list alone: the recommendations had been optimized for affordability and admission likelihood.
What the recommendation was predicting
The platform did more than look up colleges matching Marisol’s GPA. Its admission model compared her profile with historical applicants, including students with similar grades, course difficulty, test status, high school context, and intended field of study. From those patterns, it estimated the probability that each college would admit her.
A second model estimated what she might pay. It drew on published prices, past aid outcomes, family income, household information, residency, and other available signals. The platform then combined those predictions with preferences saved in Marisol’s account, including an old indication that she wanted to remain close to home.
That final step mattered most. The system was not producing a neutral catalog of colleges where Marisol could apply. It was ranking them according to a goal, and the goal favored schools that looked affordable, nearby, and likely to say yes. A college with a lower predicted admission chance and an uncertain aid estimate could fall below the display threshold, even if its aid policies might make it cheaper after an offer arrived.
This is where the story depends on the algorithm. A static spreadsheet might sort by tuition or distance, and a person could see the formula. The recommendation system inferred two uncertain outcomes, admission and net price, from previous students, then used those forecasts to decide which possibilities Marisol saw first and which she did not see at all.
The dashboard offered broad explanations for each recommendation, such as cost, distance, and academic fit. It did not show how heavily those factors had been weighted in Marisol’s ranking, nor could it explain whether the missing university had been pushed down by its predicted price, its admission estimate, or the interaction between them.
Ms. Reed put the two-page list beside her keyboard and began changing one setting at a time.
The setting that stayed behind
The distance preference came from a survey Marisol had completed earlier in high school. At the time, staying near home sounded necessary. Her parent shared a car, money was tight, and leaving the state was not something the family had discussed in concrete terms. The platform had retained that answer and treated it as a current preference.
Ms. Reed widened the travel range. Several farther colleges appeared, though the selective university still did not. She changed the affordability priority from its strongest setting to a more balanced one.
The university arrived near the bottom of the list, marked as a reach and paired with an estimated yearly cost of $29,700.
That price caught her attention. The university’s own public cost calculator, using the same basic family information, produced an estimate closer to $13,900. Neither figure was an aid offer, and both could be wrong, but the difference changed the shape of the choice. On the platform, the university looked both difficult to enter and expensive.
With the institution’s estimate beside it, the risk looked different.
Cost-prediction models can struggle with colleges that charge high published prices but give substantial need-based aid. Historical award data may be incomplete or lag behind policy changes, while an individual family’s circumstances do not always resemble the records used to train the model. The software was trying to solve a genuine problem, since students often cannot compare thousands of prices that are themselves only estimates, but its confidence was tidier than the underlying information.
The admission prediction carried a related problem. Marisol had not submitted a standardized test score, and students from her high school had rarely applied to the selective university. A model trained on prior outcomes had less evidence for a student like her. Depending on its design, limited evidence can produce a cautious estimate, especially when the historical applicant pool already reflects who had been encouraged to apply.
That creates a loop with no dramatic error message. If fewer students from a school apply to selective colleges, the system has fewer local successes to learn from. Its predictions may then make those colleges look less attainable, which can reduce future applications from the same school.
Ms. Reed wrote the platform’s $29,700 estimate on the printout, beside the $13,900 from the university calculator. The page now held two versions of practicality.
A useful list with a narrow frame
The counselor did not throw the recommendations away. One regional college on the list had a public health program Marisol had missed, along with a commuting option that could keep costs down. Another offered automatic consideration for a scholarship tied to her grades. The platform had surfaced both without requiring Ms.
Reed to search every college website after a full day of schedule changes, parent messages, and financial aid questions.
Still, reviewing the list changed her work. She had once treated the platform as a way to begin a conversation. Now she treated its ranking as something to inspect, particularly when every recommendation pointed in the same direction. Uniformity could mean a student had clear preferences.
It could also mean the system had converted one old answer and two uncertain predictions into a boundary.
For Marisol, the issue was not whether the selective university belonged on a final application list. She had limited application money, responsibilities at home, and no interest in collecting distant colleges for the sake of prestige. The immediate issue was that she had not been shown the tradeoff. The software had made one version of caution visible while leaving another version, the possibility that a well-funded college could cost less, outside the frame.
They kept six colleges from the original two-page list and added three that appeared after the settings changed. The selective university was among them. Marisol had not decided whether to apply by the time this account was assembled, and Ms. Reed had not decided how often she could repeat the same audit for other students.
The original printout remained in Marisol’s folder. The $18,400 figure was still circled. Farther down the page, Ms. Reed had added $13,900 in pencil.
Questions people ask
Why would college-planning software recommend mostly nearby schools?
Recommendation systems can combine a student’s saved distance preference with predicted admission chances and estimated cost. In Marisol’s case, an older preference to remain close to home was still active, and the ranking gave strong weight to affordability and the likelihood of admission. Together, those signals favored nearby colleges before a counselor reviewed the result.
Can an
AI estimate what a college will cost before admission?
Some planning tools estimate net price from published costs, historical aid patterns, family income, residency, and household details. The result is a prediction, not an aid offer. Marisol’s platform estimated one selective university at $29,700 a year, while the university’s public calculator produced about $13,900 using similar family information.
Does a low admission prediction mean a student should not apply?
The prediction describes how a model interpreted prior applicants and the information available in one profile. It does not decide admission. In this case, missing test data and limited history from Marisol’s high school may have made the estimate more cautious, while the printout still showed 11 nearby colleges and $18,400 circled in pencil.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.