A Neighborhood Fund Used AI. Short Requests Lost Money.
The fund had $8,400 and 73 emergency requests. Its AI ranking favored people who explained more, forcing volunteers to choose between a consistent score and their own hidden judgments.
October 6, 2026 · 7 min read
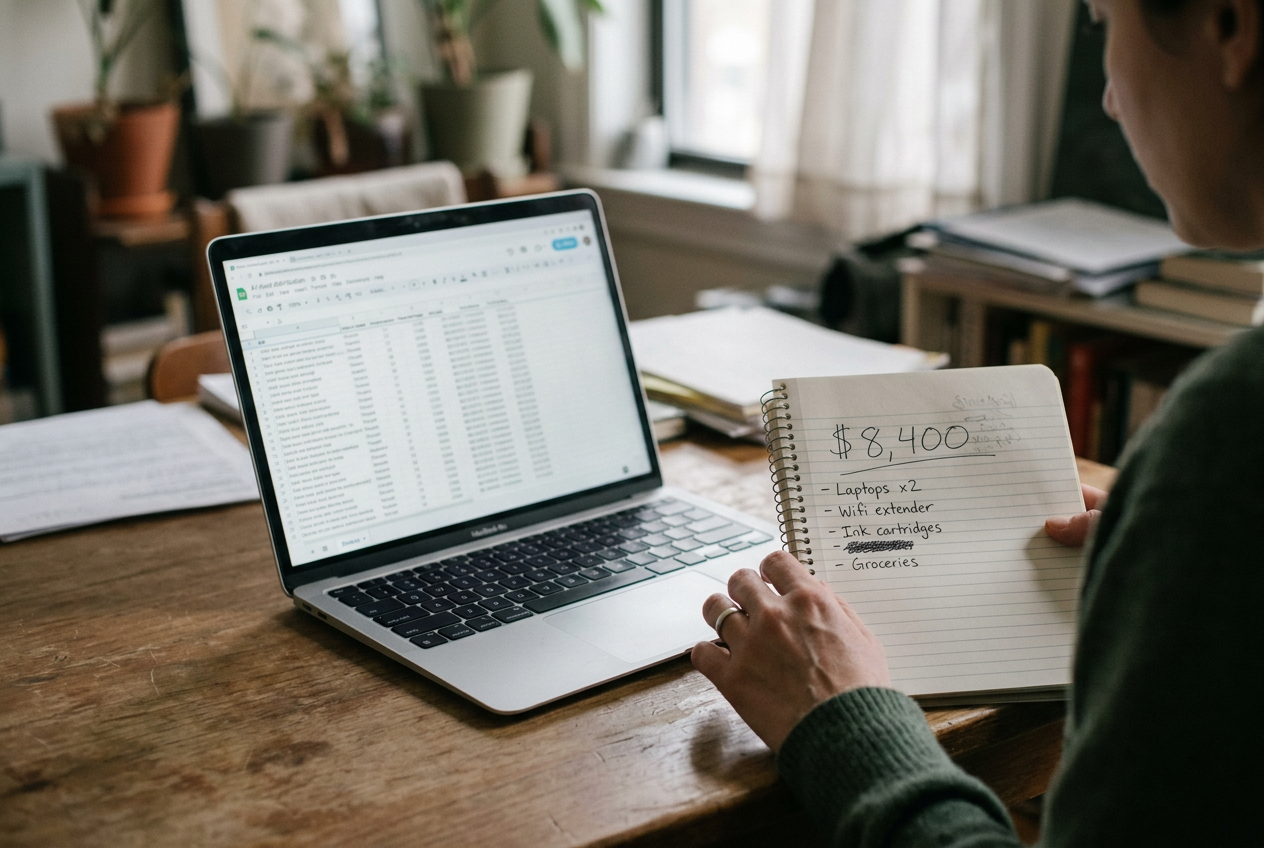
The spreadsheet had 73 rows and one column that changed how the volunteers spoke about their neighbors.
Each row represented a request for rent, groceries, medication, or a utility bill. The group had $8,400 to distribute that month, enough to cover 24 requests in full. In earlier months, volunteers had read each application during a long group call, discussed what they knew, and voted. The method took hours.
It also favored whoever could stay on the call and argue.
The new column was labeled urgency. It held a score from zero to 100, generated by an AI tool that read the written requests and applied a rubric the volunteers had supplied. The organizers hoped the ranking would give them a stable place to start, especially when the fund received more requests than its members could read together.
At first, it seemed to work. A request describing an impending utility shutoff, two missed paychecks, and medication that needed refrigeration received 82. The tool’s explanation pointed to a near deadline and the health consequence of losing electricity. Volunteers had noticed the same facts.
Farther down the spreadsheet was a request for $640 in rent. The applicant had written only that their hours had been cut and the money was needed to avoid losing housing. The score was 38.
One organizer kept returning to that row. She knew the applicant through neighborhood food deliveries and knew that short messages were normal for them. They rarely explained personal matters. The request contained an amount, a consequence, and the reason for the shortfall, yet the tool’s explanation said there was limited evidence of immediate harm.
The group had not asked the machine to punish short answers. No line in the rubric mentioned length. Still, the score placed the $640 request below applications with later deadlines and less severe consequences, provided those applicants had written fuller accounts.
That row became the argument.
What the score measured
The tool did not check bank accounts, contact landlords, or confirm shutoff notices. It received ordinary application fields, including the amount requested, the stated deadline, and a free-text explanation. A language model then matched that material against the group’s rubric and produced a score with a short rationale.
Urgency carried the most weight. Imminent harm came next. The remaining points reflected vulnerability and how specifically the applicant had described the situation. The categories looked separate on the setup screen, but the same sentence could influence more than one of them.
Mentioning a child, for example, could raise the vulnerability assessment while also making a housing loss sound more consequential.
The problem appeared in what the model did with silence. If an applicant described a shutoff date, missed work, and a medical need, the model had several textual signals to connect. If another applicant wrote only that electricity would be disconnected soon, the tool did not treat the missing details as unknown. Its rationale often treated them as missing evidence.
That distinction mattered because language models are built to find patterns in text, including patterns associated with urgency, completeness, and plausible explanation. A detailed account gives the model more phrases to map onto a rubric, even when the account has not been verified. A short account gives it fewer signals, even when every stated fact is serious.
The organizers tested the effect in the spreadsheet. They copied the $640 rent request and expanded it without changing the underlying facts. The longer version explained how reduced hours created the gap, stated that no other household income was available, and described what losing the apartment would interrupt.
The score rose from 38 to 76.
They ran 11 similar tests using requests already submitted, removing identifying details first. In nine, the longer version scored higher. Adding a sentence about an unsuccessful attempt to borrow money often raised the score, though that fact did not change the deadline or the amount owed. Replacing a general statement about illness with a more specific description also moved requests upward.
The score was consistent in one narrow sense: similar words tended to produce similar rankings. It was not consistent about need. It ranked the evidence present in the writing, along with inferences drawn from that writing, and displayed the result as though it belonged to the person rather than the paragraph.
A spreadsheet formula could sort requests by a known deadline or dollar amount. This tool did something different. It converted an applicant’s narrative into judgments about vulnerability and likely harm, including judgments the volunteers had not written as fixed rules. That was why the group could process 73 requests quickly.
It was also why the short request fell.
The argument over consistency
Several volunteers wanted to keep the scoring system. Before it existed, the loudest member of a meeting could move a request upward by describing a family they knew, while unfamiliar applicants remained entries on a screen. Personal relationships had always affected the fund. The scores made at least part of the decision visible in the spreadsheet.
One volunteer called the old process memory plus persuasion. To her, abandoning the tool would not remove bias. It would restore a version nobody could audit.
Others thought the ranking had formalized the group’s least examined assumptions. Applicants who wrote in detail received credit for facts, context, and emotional legibility. People who protected their privacy, had limited English, or assumed a neighbor would understand the problem were more likely to leave the model with less material. The tool then turned that difference into a precise number.
The dispute was not between people who trusted machines and people who trusted human judgment. Several critics had helped write the rubric because they were tired of decisions changing with attendance. Some supporters of the tool agreed that 38 was indefensible. They differed over whether the failure could be repaired without returning to meetings where relationships quietly counted.
For two months, the group stopped using the score to set the payment order. They kept the spreadsheet and used the model for a narrower task: extracting stated deadlines and flagging requests that lacked information needed for review. An absent detail appeared as unknown rather than becoming a reason to subtract points. Volunteers still read every request selected for funding.
That change reduced the tool’s authority, but it also brought back work the organizers had hoped to avoid. Applications piled up. Two volunteers left the review group, saying the meetings had become unmanageable again. Another stayed because the extracted deadlines helped her find requests that might otherwise sit unread.
The $640 request was funded from the next round. The applicant was not told that an expanded version of their explanation had nearly doubled an AI score. Organizers disagreed about whether sharing that fact would offer useful transparency or pressure people to disclose more the next time they needed help.
They also kept the original scoring column. Some wanted a record of the test. Others expected to revise the rubric and try again after collecting more examples of concise requests. The score of 38 remained beside the final payment entry, even after the group had decided not to use it.
Questions people ask
Why did longer emergency requests receive higher AI scores?
The model scored the text against concepts such as urgency, vulnerability, and likely harm. Longer requests supplied more phrases that could support those concepts. When details were absent, the tool often treated the application as having weak evidence rather than recognizing that the applicant might be concise or private.
Was the
AI checking whether applicants told the truth?
No. It did not verify income, deadlines, household circumstances, or notices from a landlord or utility. It judged how well the submitted words matched the rubric. A detailed account could therefore score well because it was legible to the model, not because its claims had stronger outside support.
Did removing the score make the fund fairer?
The volunteers did not settle that question. Removing the ranking stopped concise writing from directly lowering payment priority, but it restored long meetings in which familiarity and persuasion could influence decisions. The group kept AI extraction for deadlines while people reviewed the requests themselves.
Can the same facts receive different scores?
They did in the group’s test. Expanding an account without changing its central facts raised nine of 11 scores, including the rent request that moved from 38 to 76. Both numbers remain in the saved test sheet beside the same $640 need.
One story a day
The story of the day, in your inbox
One real story about AI each morning — no hype, no alarm, just company for the road.